McKinsey’s 2022 State of Customer Care report notes that most contact centers review fewer than 5% of customer conversations manually. That’s the problem the speech analytics industry was built to solve and it’s a real problem. But most teams that deploy AI speech analytics discover a second version of it within six months: they now have analysis covering 100% of conversations, and they’re still only acting on a small fraction of the insights it produces.
The bottleneck shifts. Before deployment, the constraint is data, most interactions go unexamined. After deployment, the constraint is triage, alerts fire constantly, dashboards accumulate scores, and managers face more data than they can respond to without a structured process for deciding what to act on first. The platforms that solve the first problem but make the second one worse are not actually improvements.
This guide is built around that distinction. The platform comparison focuses specifically on how each tool helps teams act on what they find, not just how thoroughly it finds things. That’s the capability that separates platforms worth buying from platforms worth demoing.
Key Takeaways
- AI speech analytics software helps contact centers analyze 100% of customer conversations instead of manually reviewing only small call samples.
- The biggest challenge after deployment is not collecting insights, but prioritizing and acting on them effectively.
- Speech analytics relies on ASR, NLP, and machine learning to detect sentiment, compliance risks, customer intent, and performance trends.
- Transcription accuracy is critical because poor ASR performance creates false alerts, unreliable sentiment analysis, and missed compliance risks.
- Real-time analytics supports live agent guidance and compliance monitoring, while post-call analytics focuses on QA, trend analysis, and root-cause discovery.
- Key capabilities include auto QA scoring, real-time agent prompts, compliance monitoring, sentiment analysis, and churn signal detection.
- TabaTalk stands out for real-time guidance and strong Arabic/GCC transcription accuracy, making it ideal for live support and compliance-heavy environments.
- Voiso offers faster deployment with built-in contact center infrastructure, while NICE CXone provides enterprise-scale depth and CallMiner excels in historical analytics.
- Choosing the right platform depends on where operational losses occur, required compliance coverage, transcription accuracy, workflow ownership, and total deployment costs.
- Successful implementation depends more on coaching workflows, operational ownership, and structured insight-to-action processes than the platform itself.
- Organizations see the fastest ROI through QA efficiency gains, while conversion improvements and churn reduction require long-term optimization and coaching.
- The most successful speech analytics deployments combine AI insights with structured coaching, continuous ASR calibration, and clearly defined operational accountability.
In short, AI speech analytics platforms help contact centers improve compliance, agent performance, and customer experience, but long-term success depends on turning insights into measurable operational action.
What AI speech analytics actually does and where accuracy problems appear
The core technical pipeline is straightforward: calls get recorded, automatic speech recognition (ASR) converts audio to text, and natural language processing (NLP) identifies intent, sentiment, keyword patterns, and topic clusters across the transcript. Machine learning models then surface patterns across large call sets, identifying agent behaviors that correlate with high resolution rates, phrases that precede cancellations, compliance disclosures that are missing or incorrectly delivered.
Where this breaks down in practice is almost always ASR accuracy, and vendors rarely discuss it plainly. Transcription accuracy drops with background noise, strong accents, domain-specific terminology, and simultaneous speech (interruptions, talking over each other). A platform claiming 90% accuracy in lab conditions may deliver 75–80% on a live contact center floor with agents handling complex technical products in regional dialects. At 80% accuracy, roughly one word in five is wrong, which is sufficient to generate false compliance alerts, miss genuine risk phrases, and produce sentiment scores that don’t reflect the actual call.
The practical test: ask any vendor to run their platform on a sample of your actual calls before purchase, not their curated demo recordings. Accuracy on your specific call types, accents, and product vocabulary is the only accuracy number that matters. Vendors that won’t run a live accuracy test on your data before a sale are the ones with the most to hide from it.
Real-time vs post-call: different problems, not just different timing
Real-time speech analytics processes audio during the live conversation and surfaces guidance or alerts to the agent while the call is still in progress. Post-call analysis processes recordings after the call ends and feeds insights into QA scoring, trend reports, and coaching queues. These aren’t faster and slower versions of the same thing, they address fundamentally different failure modes.
| Dimension | Real-time | Post-call |
| What it prevents | Compliance gaps before the call ends; lost sales from poor handling of objections | Repeat patterns across many agents; systemic script failures; long-term churn signals |
| What it requires | Low latency infrastructure; high ASR accuracy under live pressure; agent screen integration | High analytical depth; pattern recognition across large datasets; robust reporting tools |
| Where it breaks down | Latency spikes make guidance irrelevant; low accuracy generates noise agents learn to ignore | Analysis arrives too late to affect the finished call; insights require a coaching process to reach agents |
| Who benefits most | Sales teams, compliance-heavy operations, high-volume inbound with script requirements | QA teams, operations managers running root-cause analysis, workforce planners |
Most operations need both, but the emphasis depends on where performance losses are occurring. A sales floor losing deals to objection handling at the moment of decision needs real-time guidance. A support center with rising repeat-contact rates needs post-call pattern analysis to understand why first-contact resolution is failing. Platforms that claim to do both well warrant scrutiny on whichever one is secondary to their core design.
The features that actually change performance outcomes
Most speech analytics platforms list similar capabilities. The difference is in implementation depth, specifically, whether features connect to operational workflows or just add to dashboard complexity.
Auto QA scoring
Automated quality scoring evaluates every call against predefined criteria and produces a score without manual reviewer involvement. Done well, this eliminates sampling bias (reviewers tend to pull calls they expect to be good or bad, not a representative set) and gives managers a complete picture of team performance rather than 10 calls per agent per month.
Done poorly, it produces a score nobody trusts because the criteria weren’t calibrated carefully or the ASR accuracy is too low for the scoring to be reliable. Before assuming auto QA is working, compare a sample of automated scores against human reviewer scores for the same calls. Systematic divergence, auto scores consistently higher or lower than human scores, or high variance on calls humans rate similarly, indicates a calibration problem.
Real-time agent guidance
Real-time prompts appear on the agent’s screen during a live call, triggered by detected keywords, sentiment shifts, or conversation stage. The value is in specificity: a prompt that appears when a customer says a competitor’s name and shows a relevant comparison talking point is useful. A prompt that fires when sentiment drops and says ‘try to de-escalate’ is not.
The implementation requirement most vendors underemphasize: agent adoption. Agents who find guidance irrelevant or distracting will develop the habit of ignoring it within two weeks, and once that habit forms it’s hard to reverse. The onboarding process for real-time guidance needs to include agent feedback loops on prompt quality from the first week. Platforms that make prompt configuration easy give operations teams the ability to iterate quickly based on what agents actually find useful.
Compliance monitoring
Compliance monitoring tracks whether required disclosures, consent language, or regulatory phrases were delivered on every applicable call. In financial services, healthcare, and regulated sales environments, this replaces manual audit sampling with continuous monitoring, meaning gaps get caught within hours of occurring rather than at the next quarterly audit.
The limitation worth knowing: compliance monitoring is only as good as the phrase library it’s checking against. Most platforms come with generic compliance templates. Teams in specific regulatory environments, FCA-regulated UK financial services, SAMA-regulated Saudi banking, state-specific US insurance regulations, need to configure the phrase library for their specific requirements, which takes time and ongoing maintenance as regulations change.
Sentiment and churn signal detection
Sentiment analysis tracks emotional tone across calls and flags interactions where customer frustration is rising or correlates with known churn patterns. The quality of this feature varies more than vendors suggest. Basic sentiment detection identifies positive and negative language at the word level, ‘frustrated’, ‘disappointed’, ‘cancel’. More sophisticated models detect sentiment through prosody (tone and pacing, not just words) and context (sarcasm, hedged cancellation language that doesn’t use the word ‘cancel’).
Churn signal detection requires training data from your specific business, the phrases and behavioral patterns that precede cancellations for your product, in your market, with your customer base. Out-of-the-box churn models trained on generic data from other industries are a starting point, not a finished capability. Ask vendors specifically whether their churn models are pre-trained or whether they require calibration on your historical data, and how long that calibration process takes.
Platform comparison: what each one has actually built
The comparison below is organized around design philosophy and genuine trade-offs. All four platforms cover the core features. The differences are in what each one optimizes for and what that means operationally.
TabaTalk: strongest fit for real-time guidance in GCC markets
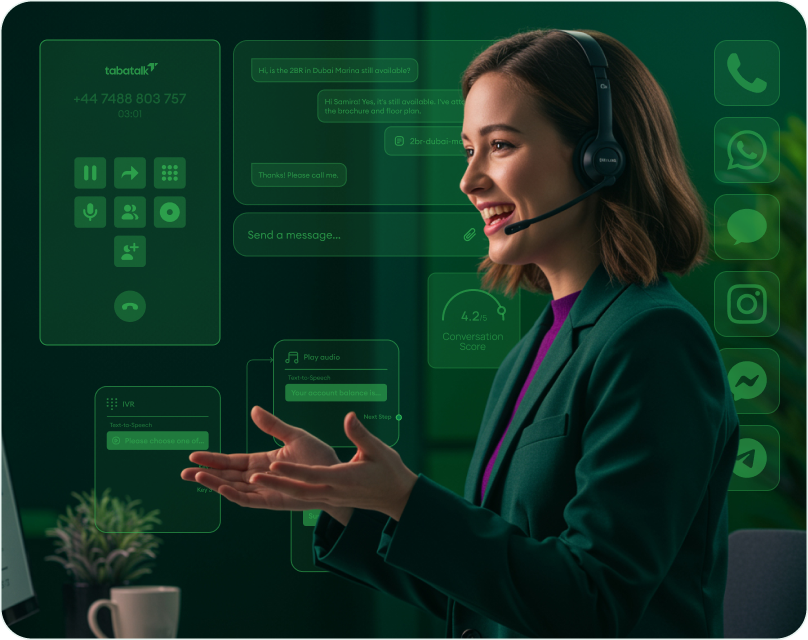
TabaTalk’s design priority is agent support during live conversations rather than post-call analysis depth. The platform processes calls with low enough latency to surface useful guidance before agents need to respond, which is the technical constraint most real-time platforms struggle with. Guidance adapts to conversation context rather than firing on keyword matches alone, the distinction matters because keyword-only prompts generate too much noise for agents to take seriously.
Transcription accuracy across Arabic dialects and GCC-market English is a specific strength. Most platforms with strong English accuracy drop significantly on regional dialects; TabaTalk’s infrastructure reflects where its customer base operates, which translates to more reliable compliance monitoring and sentiment detection in those markets.
Where it genuinely falls short: post-call historical analytics depth. Teams that need sophisticated root-cause analysis across large call datasets, complex custom reporting, or enterprise workforce management integration will find TabaTalk’s post-call capabilities less developed than CallMiner or NICE CXone. The platform’s prioritization is explicit, real-time guidance first, historical depth second. That’s the right trade-off for its target buyer; it’s a real limitation for teams whose primary need is retrospective pattern analysis.
Voiso: fastest deployment, contact center infrastructure included
Voiso’s speech analytics sits inside a broader contact center platform rather than being a standalone analytics tool. That means teams get call routing, agent management, and analytics from a single vendor, which simplifies procurement and reduces integration complexity. The deployment timeline is genuinely shorter than specialized analytics platforms because there’s no external system integration required.
The trade-off is analytical depth. Voiso’s speech analytics covers the core use cases well: auto QA, basic sentiment, keyword tracking, and compliance phrase monitoring. Teams that need advanced pattern recognition across large historical datasets, complex custom scoring models, or deep integration with third-party BI tools will hit capability ceilings that specialized platforms don’t have. For contact centers that are deploying speech analytics for the first time and want to build the capability without a months-long implementation project, Voiso is a practical starting point. For teams replacing a mature analytics stack, it may not match the depth they’re used to.
NICE CXone: enterprise depth, enterprise complexity
NICE CXone has the most feature-complete analytics suite in this comparison. Workforce management integration, advanced forecasting, compliance frameworks for multiple regulatory environments, and a configurable analytics layer that covers use cases most mid-market platforms don’t support. For a global enterprise managing high call volumes across multiple jurisdictions with internal resources to manage platform complexity, it’s the strongest option.
That complexity is real. NICE CXone implementations at enterprise scale typically require months, dedicated internal ownership, and ongoing configuration management. Teams that are evaluating it should get concrete timelines from reference customers in their size range, not deployment estimates from the vendor, which are almost always optimistic. The platform also prices accordingly; it’s often cost-prohibitive for teams under 200 agents unless the use case requires capabilities that have no mid-market equivalent.
CallMiner: the deepest post-call analytics in this group
CallMiner is built around historical analysis: finding patterns across large call datasets, building custom scoring models, and producing the kind of root-cause reporting that explains why performance is trending in a particular direction. The search and query capabilities are more granular than the other platforms here, analysts can build complex searches across transcript data, filter by conversation characteristics, and produce reports that connect call behavior to business outcomes.
The real-time capability is limited. CallMiner’s design assumption is that analysis happens after calls, not during them. Teams that need live agent guidance or real-time compliance alerts during conversations will find the platform’s real-time layer thin relative to its historical depth. For QA-focused operations, analytics teams, and organizations where the primary job is understanding why things are happening rather than intervening as they happen, CallMiner’s depth is a genuine advantage.
How to choose: the criteria that actually differentiate these platforms
The five questions that reliably separate which platform fits a specific operation aren’t about features, they’re about where your current performance problems actually sit and what kind of intervention reaches them.
Where are your losses occurring: during calls or after them?
If agents are losing sales at specific moments in the conversation, or compliance gaps are occurring because agents are forgetting required disclosures under call pressure, the loss happens during the call. Real-time guidance has a chance to change the outcome. If the problem is systematic, agents across the team handling a particular call type poorly, scripts that don’t work for a specific customer segment, churn patterns that aren’t being caught, the loss accumulated before any individual call started. Post-call analysis is what surfaces that.
Most operations have both, but one is more urgent. The answer determines whether real-time capability is the primary criterion or a secondary one.
What does your compliance environment actually require?
Generic compliance monitoring covers generic requirements. If your operation runs in a specific regulatory environment, financial services, healthcare, telecoms with sector-specific rules, ask each vendor to show you their compliance library for your specific jurisdiction and walk through how phrase libraries get updated when regulations change. The answer to that second question is often more revealing than the first.
What’s your transcription accuracy floor?
Set a minimum accuracy threshold before evaluating platforms. For compliance monitoring, 90%+ accuracy on your specific call types is the practical minimum, below that, the false positive rate on compliance alerts becomes operationally disruptive. For sentiment analysis, 85% is a reasonable floor. For keyword-triggered real-time guidance, 88%+ keeps the noise level manageable for agents.
Run a paid proof-of-concept on 500 of your own calls before committing. Most vendors will do this. The ones that won’t are telling you something.
What happens to insights after the platform generates them?
This is the question the original article doesn’t ask, and it’s the one that determines whether the platform actually improves performance or just produces more data. If auto QA scores go into a dashboard that nobody reviews, they don’t improve anything. If sentiment alerts fire and there’s no protocol for who responds to them and how quickly, the real-time capability is wasted.
Before selecting a platform, map the workflow from insight generation to agent behavior change. Who sees the alert? In what time window? What action do they take? Who verifies that the action happened? If that workflow doesn’t exist yet, the platform selection should wait until it does, or the platform selection should include the process design as part of the implementation.
What’s your actual budget for the full deployment, not just the license?
Enterprise platforms charge for the license and assume the implementation cost is separate. Mid-market platforms often bundle setup but charge for integrations. The total cost of deployment, including integration with your telephony platform, CRM, and workforce management tools, plus the time your team will spend on configuration, training, and ongoing management, typically runs 40–80% of first-year license cost on top of the license. Build that into the budget comparison before shortlisting.
What results to realistically expect and how the ranges get misused
The benchmarks that circulate in speech analytics marketing, 20–30% cost reduction, 10–15% conversion improvement, come from real research but get stripped of context that makes them meaningful. McKinsey’s figures on AI-driven operational cost reduction (from their 2022 State of Customer Care report) are drawn from operations that deployed AI across multiple automation layers, not speech analytics alone. Forrester’s conversion improvement figures (from their 2021 Contact Center AI Playbook) are from sales environments with high-volume outbound calling where real-time guidance had maximum opportunity to influence outcomes.
Neither number is wrong. Both are misleading when attached to a generic ‘results you can expect’ claim without specifying the operational conditions that produced them.
The more useful frame: speech analytics ROI appears first and most reliably in QA efficiency, the reduction in time spent on manual call review when auto QA covers 100% of calls. That’s a calculable number before deployment: current QA cost (reviewer hours × hourly cost) versus platform cost plus the reduced reviewer hours needed for calibration and exception handling. For most mid-sized operations, QA efficiency alone justifies the platform cost.
Compliance risk reduction is the second area where impact is measurable but harder to quantify before a breach occurs. The value depends on what a compliance failure costs in your specific regulatory environment. For FCA-regulated financial services, a single compliance failure can carry fines in the millions; automated monitoring that catches gaps before audits has obvious value. For a retail e-commerce support team, the same feature has marginal relevance.
Conversion improvement and churn reduction take longer to materialize and depend heavily on whether the coaching process connected to the platform is working. Teams that see the 10–15% conversion improvements in Forrester’s data have typically spent 3–6 months calibrating their real-time guidance, training agents to use it, and iterating on what prompts actually help versus which ones create noise. Expecting that result in the first quarter of deployment is not a realistic planning assumption.
Implementation: the decisions that determine whether it works
The implementation steps for speech analytics are not complex, integrate the platform with your call recording system, configure the tracking criteria, train users, and deploy. Most vendors can walk you through that process in a day. The decisions that actually determine whether the platform improves performance are different from the technical setup steps.
Start with one use case, measure it, then expand
The most common implementation failure is configuring the platform for everything simultaneously, compliance monitoring, auto QA, sentiment analysis, real-time guidance, churn detection and then having no way to attribute any performance change to any specific capability. Start with the single use case that addresses your most urgent problem. Measure the baseline before deployment. Measure again at 60 days. Expand to additional use cases once the first one is working and the measurement methodology is established.
The coaching loop is the implementation
A speech analytics platform that generates QA scores, sentiment trends, and coaching flags but isn’t connected to a structured coaching process doesn’t change agent behavior. The technology surfaces where the problems are; the coaching process is what fixes them. Before deployment, decide how often supervisors will review auto QA scores with agents, what the format for those conversations looks like, and how long after a call a coaching interaction should happen to be effective. Deloitte’s 2023 Global Contact Center Survey found that organizations combining AI-generated insights with structured weekly coaching conversations saw significantly faster performance improvement than those using the same insights without a defined coaching cadence.
ASR calibration is ongoing, not a one-time setup
Transcription accuracy on your call types will be highest after calibration and drift over time as agents change, products change, and call types evolve. Build a quarterly accuracy review into the platform management process, comparing automated scores against human review on a sample of recent calls. Accuracy below the thresholds you set during evaluation is a signal that the model needs retraining, not that the platform has stopped working.
The question that predicts whether the deployment will work
After evaluating platforms, running accuracy tests, and confirming integration feasibility, the most reliable predictor of whether a speech analytics deployment succeeds isn’t the platform at all. It’s whether the organization has a clear answer to: who owns the insight-to-action workflow, and what happens to their performance if insights aren’t being acted on?
Platforms that generate insights without an owner for those insights produce dashboards that nobody checks. This isn’t a technology failure, it’s an organizational design gap that technology can’t fix. The teams that get the most from speech analytics are the ones that treated platform selection as the last step of a process that started by designing that workflow, assigning ownership, and defining what ‘acting on an insight’ actually means in their environment.
TabaTalk’s real-time guidance layer is most valuable to teams that have already built that operational structure, where supervisors have defined protocols for coaching, agents have been trained on how to use on-screen prompts, and there’s a feedback loop for improving guidance quality over time. Deployed into an organization without that structure, even the best real-time platform produces alerts that get ignored.
If that structure doesn’t exist yet, building it is the implementation. The platform choice matters less than it seems until that work is done.